Showing posts with label CDI. Show all posts

Wednesday, February 07, 2007

Probabilistic Matching

Probabilistic matching uses likelihood ratio theory to assign comparison outcomes to the correct, or more likely decision.

Probabilistic matching enables one to use match scores and percentages on a field by field comparison to determine a match. There are three categories output from probabilistic matching and are set by the user based on the overall probability percentage:

1) Match - that can be automatically merged
2) Candidate Match - requiring manual review
3) Non Match

Artificial Intelligence and Machine Learning utilize probabilistic matching.

Tuesday, February 06, 2007

Service Oriented Architecture (SOA)

A service-oriented architecture is a collection of services that communicate with each other. The services are self-contained and do not depend on the context or state of the other service. They work within a distributed systems architecture.

Record Linkage

Record linkage is the act of detecting and linking duplicate records within a database. It is also called match/merge, deduplication, match/consolidate, etc.

Some record linkage software tools include:
Febrl (Freely Extensible Biomedical Record Linkage) - Open Source
TAILOR
TheLinkKing
MatchIT - Commercial
Business Objects - Commercial
Group1 - Commercial

Fuzzy Matching Logic

A method of matching where algorithms are used to compare character strings and detect recurring patterns within these strings. Common algorithms are Soundex, Levenshtein Distance and Double Metaphone which find similarities based on patterns and similarities. It is called a "fuzzy match" because the match is not exact, like if you were looking at the two records out of focus, they would look the same, but would be a bit fuzzy.

Enterprise Resource Planning (ERP)

Software that integrates departments and functions across a company into one computer system. ERP runs off a single database, enabling various departments to share information and communicate with each other. It helps a manufacturer or other business manage the important parts of its business, including product planning, parts purchasing, maintaining inventories, interacting with suppliers, providing customer service, and tracking orders.

Customer Data Integration (CDI)

Customer Data Integration (CDI) is the consolidation and management of customer data from all available sources. This customer data typically includes contact details, value data, and other information collected across multiple channels and through various interactions. The purpose of CDI is to keep source data systems and the central database in synch with each other to provide an accurate central view of each customer

Customer Relationship Management (CRM)

The functions and programs a company uses to connect with its customers - typically divided into Operational CRM (call centers, sales force automation, supply chain management) and Analytic CRM (customer analysis, database marketing). It allows an individual approach to marketing to and servicing customers.

Sunday, February 04, 2007

CDI - Glossary of Terms

As I've mentioned before, a primary barrier to studying any subject is the misunderstood word. Per Hubbard's study technology site:

"To clear a word, one looks it up in a good dictionary.

"The first step is to look rapidly over the definitions to find the one which applies to the context in which the word was misunderstood. One reads the definition and uses it in sentences until one has a clear concept of that meaning of the word. This could require ten or more sentences.

"Then one clears each of the other definitions of that word, using each in sentences until one has a conceptual understanding of each definition.

"The next thing to do is to clear the derivation – which is the explanation of where the word came from originally. This will help gain a basic understanding of the word." ...
- L. Ron Hubbard
Therefore I've started putting together simple to understand definitions for the most common terms in the field of Customer Data Integration.
Customer Relationship Management (CRM)

Customer Data Integration (CDI)
Enterprise Resource Planning (ERP)
Fuzzy Matching Logic
Probabilistic Matching Logic
Record Linkage

Service Oriented Architecture (SOA)

Monday, January 29, 2007

Record Linkage Graphical User Interfaces

Manual handling of duplicates in a database can be quite time consuming. It is important to find the right tool to help you speed this process. Or if you are building your own record linkage tool, it is always good to see what is out there, how GUIs are laid out and what the common features are.

The Link King:


The Link King’s graphical user interface (GUI) makes record linkage and unduplication easy for beginning and advanced users. The data linking neophyte will appreciate the easy-to-follow instructions. The Link King's artificial intelligence will assist in the selection of the most appropriate linkage/unduplication protocol.

Linkage Wiz:


LinkageWiz
is a powerful data matching and record de-duplication software program used by businesses, government agencies, hospitals and other organisations in the USA, Canada, UK, Australia and France. It makes it easy to link records across multiple databases and to identify and remove duplicate records within databases
TAILOR -
TAILOR is extensible, and hence any proposed searching method, comparison function, decision model, or measurement tool can be easily plugged into the system. We have proposed three machine learning record linkage models that raise the limitations of the existing record linkage models. Our extensive experimental study, using both synthetic and real data, shows that the machine learning record linkage models outperform the probabilistic record linkage model with respect to the accuracy and the completeness metrics, the probabilistic record linkage model identifies a lesser percentage of possibly matched record pairs, both the clustering and the hybrid record linkage models are very useful, especially in the case of real applications where training sets are not available or are very expensive to obtain, and Jaro's algorithm performs better than the other comparison functions.

The following three screen snapshots are the basic screens of TAILOR graphical user interface. The first screen allows the user to either generate a synthetic experiment using DBGen, perform a real experiment on a database, or repeat a previous experiment knowing its data files. The user then uses the second screen in order to select a searching method and a comparison function and tune their required parameters. Finally, the third screen allows the user to select the decision model he would like to apply and outputs the values of the measures if the experiment is on synthetic data.

Download PDF for screenshots of TAILOR here.

MatchIT -
matchIT incorporates our proprietary matching algorithms to ensure phonetic, miskeyed and abbreviated variations of data are detected. Results can be verified using comprehensive data auditing functions, drilling down to suspect data, identifying data anomalies, and filtering garbage and salacious words.


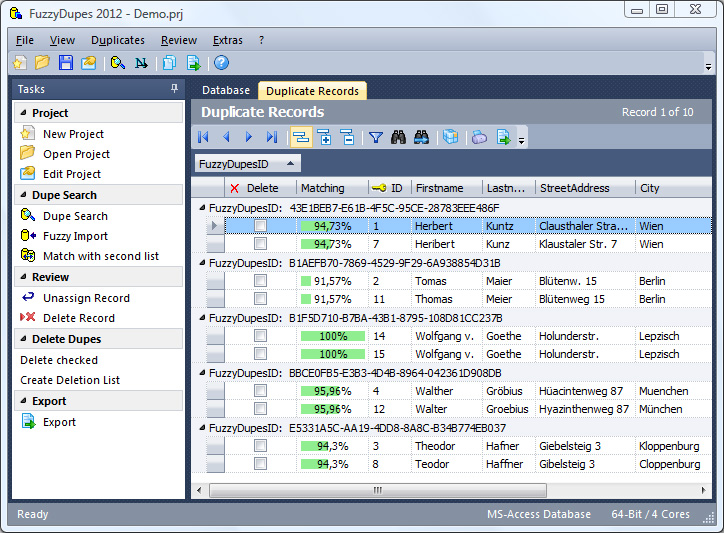
Fuzzy Dupes 2007

Did you know that your contact database typically contains 3-10% duplicates ?

These duplicate records result in unnecessary costs when sending out printed catalogs, are aggravating to your customers, create problems in the controlling, etc. With classical methods you have no possibility to locate these duplicates in your database.


Sunday, January 28, 2007

Record Linkage and List Quality

What is Record Linkage:

Record linkage is the task of quickly and accurately identifying records corresponding to the same entity from one or more data sources. Record linkage is also known as data cleaning, entity reconciliation or identification and the merge/purge problem. This paper presents the “standard” probabilistic record linkage model and the associated algorithm. Recent work in information retrieval, federated database systems and data mining have proposed alternatives to key components of the standard algorithm. The impact of these alternatives on the standard approach are assessed. The key question is whether and how these new alternatives are better in terms of time, accuracy and degree of automation for a particular record linkage application.


Other names that mean the same thing: entity heterogeneity, entity identification, object isomerism, instance identification, merge/purge, entity reconciliation,
list washing, match/consolidate and data cleaning. I like the term "record linkage" and will refer to it as such from this point forward in this blog.

Seems clear that if you want to be thorough in your record linkage efforts you would implement a combination of deterministic and probabilistic matching methodologies. Using a straightforward name and address match such as the Firstlogic (now Business Objects) approach will usually be sufficient if you are a list vendor or mailhouse. But if you are at all serious about identity management you will step into the deep end and implement a probabilistic matching method. I've downloaded the Ferbl open source probablistic matching tool, but have yet to experiment with it.

But whatever method you use or software package you buy, the quality of your record linkage always ends up in how good you have configured your rules. This is not an off-the-shelf solution - it requires work.

I bet most organizations "record linkage problems" could have been avoided if enough forsight and initiative had been put on the original database systems, in establishing that unique key.

Well, I guess hindsight is in fact - 20/20.

One product that definitely contributes to an increased percentage of record linkage is the SSA-NAME3 product. As you'll see from their site, they have developed this name search tool which uses probabilistic matching but factors in how common or uncommon the name is. For example matching two Jose Garcia's in the city of Los Angeles is not the same as matching two Jose Garcia's in Iceland. They are probably the same person in Iceland and most likely not, in LA.

What is a Data Steward?

Data Steward defined:

The person responsible for a data standard. In this role, a Data Steward is charged by his/her Management to develop and maintain the data standard and to counsel Service personnel on the proper use of the data. He/she must: have a thorough knowledge of the subject matter of the standard, provide accurate and current electronic copies of data relevant to the standard, and weigh the pros and cons of comments received during review of the standard. He/she is authorized to defend or modify the standard as necessary in order to ensure its proper use.
Claudio Imhoff's definition and description of duties:
Steward - from Old English for "keeper of the sty", a sty ward.

Data Steward - Person responsible for managing the data in a corporation in terms of integrated, consistent definitions, structures, calculations, derivations, and so on.

Corporations are demanding better and better sources of data. The explosive growth of data warehousing and sophistication of the access tools are proof that data is one of the most critical assets any company possesses. Data, in the form of information, must be delivered to decision-makers quickly, concisely and more importantly, accurately.

The data warehouse is an excellent mechanism for getting information into the hands of decision-makers. However, it is only as good as the data that goes into it. Problems occur when we attempt to acquire and deliver this information. A major effort must be made in defining, integrating and synchronizing the data coming from the myriad operational systems producing data throughout the corporation. Who should be responsible for this important task? The answer for a growing number of companies is a new business function called Data Stewardship.

What is Data Stewardship?

Data Stewardship has, as its main objective, the management of the corporation's data assets in order to improve their reusability, accessibility, and quality. It is the Data Stewards' responsibility to approve business naming standards, develop consistent data definitions, determine data aliases, develop standard calculations and derivations, document the business rules of the corporation, monitor the quality of the data in the data warehouse, define security requirements, and so forth (see Table 1 for a list of the data integration issues determined by Data Stewards).

This data about data, or meta data, developed by Data Stewards can then be used by the corporation's knowledge workers in their everyday analyses to determine what comparisons should be made, which trends are significant, that apples have indeed been compared to apples, etc.

Just as the demand for a data warehouse with good data has grown, the need for a Data Stewardship function has likewise grown. More and more companies are recognizing the critical role this function serves in the overall quest for high quality, available data. Such an integrated, corporate-wide view of the data provides the foundation for the shared data so critical in the data warehouse. ...

Data Stewards are responsible for the following:
* Standard Business Naming Standards
* Standard Entity Definitions
* Standard Attribute Definitions
* Business Rules Specification
* Standard Calculation and Summarization Definitions
* Entity and Attribute Aliases
* Data Quality Analyses
* Sources of Data for the Data Warehouse
* Data Security Specification
* Data Retention Criteria
Crash Course on Data Stewardship:

Data Stewardship programs are implemented to reduce information technology costs and improve the value companies gain from their data assets. Stewardship programs focus on improving data quality, reducing data duplication, formalizing accountability for data, and improving business and IT productivity. An effective Data Stewardship program will rapidly improve the ROI from data warehousing and business intelligence efforts

Data Governance - IT or Business?

"Where does Data Governance fit into the Organization?"

This question appears to have two answers. "In Business" or "In IT". The answer I get most often when I ask the question is ... "In Business". Or "Business should own Data Governance".

I wish it was that simple.

What exactly does it mean for Data Governance to fit "In Business"?

This article seemed to take up the questions posed in my last post. The last paragraph sums it up and answers this question.

The best answer to the question "Where does Data Governance fit into the Organization?" is "It doesn't matter". Data Governance can be successful when managed by a business area or by an IT area.

The decision of who will manage the Data Governance program can be very important to the success of the program. However, it will not necessarily make or break a well-defined Data Governance program's likelihood of success. As long as the business areas and IT areas coordinate their efforts, use a Data Governance Council as a strategic resource, cooperate in strategic data management activities, and act in the best interests of the organization (data-wise), the placement of the management of the Data Governance program is not nearly the most important question that needs to be answered.

Wednesday, January 24, 2007

IT Departments Role in CDI

Introducing Customer Data Integration into an organization can be a bit daunting. A recommendation to anyone doing this is Jill Dyche / Evan Levy's book: Customer Data Integration which definitely builds the needed foundation for anyone's understanding of this subject. However, there are still aspects that need to be understood and certain functions clearly delineated.

What is the role of IT in CDI (Customer Data Integration)?

First a definition of IT:

information technology
n. Abbr. IT
The development, installation, and implementation of computer systems and applications.
"IT." The American Heritage® Dictionary of the English Language, Fourth Edition. Houghton Mifflin Company, 2004. 24 Jan. 2007. http://dictionary.reference.com/browse/IT>
The development, installation and implementation of the CDI system is the responsibility of IT - Not the day-to-day upkeep of the data. As a Data Steward you must have the needed access to the data in order to uphold your responsibilities.

Tight coordination is needed between the Data Stewards and the IT Dept when the CDI project is in its early stages. Clear definitions should be established for the roles needed, responsibilities assigned and the needed functionality and access levels built into the CDI project.

Getting this established and clearly delineated at the onset is critical to a successful CDI implementation and will increase the mileage and speed of progress in achieving your goals with CDI.

Monday, January 15, 2007

Machine Learning and Artificial Intelligence

Machine Learning is a topic that has come up a lot during my CDI (Customer Data Integration) research. Specifically when diving into the domain of Probabilistic Matching. From the Initiate website:

Probabilistic matching

Probabilistic matching uses likelihood ratio theory to assign comparison outcomes to the correct, or more likely decision. This method leverages statistical theory and data analysis and, thus, can establish more accurate links than deterministic systems between records that have more complex typographical errors and error patterns.

Typically, probabilistic systems assign a percentage (such as 75 percent) indicating the probability of a match. Because these systems pinpoint variation and nuances to a much finer degree than a deterministic approach, they are better suited for businesses that have complex data systems with multiple databases. Due to the size of these data systems, the potential for duplicates, human error and discrepancies is far greater, making a system designed to establish links between records with complex error patterns much more effective.
Probabilistic matching enables one to use match scores and percentages on a field by field comparison to determine a match. There are three categories output from probabilistic matching and are set by the user based on the overall probability percentage:

1) Match - that can be automatically merged
2) Candidate Match - requiring manual review
3) Non Match

The topic of Machine Learning and artificial intelligence enters in with the manual review process of the candidate matches. The idea is that computer can learn from the users decisions of what was manually determined to be a match or non-match and build these into its future decisions and probability scores.

If an expert system--brilliantly designed, engineered and implemented--cannot learn not to repeat its mistakes, it is not as intelligent as a worm or a sea anemone or a kitten.
-Oliver G. Selfridge, from The Gardens of Learning.

"Find a bug in a program, and fix it, and the program will work today. Show the program how to find and fix a bug, and the program will work forever."
- Oliver G. Selfridge, in AI's Greatest Trends and Controversies

Machine learning refers to a system capable of the autonomous acquisition and integration of knowledge. This capacity to learn from experience, analytical observation, and other means, results in a system that can continuously self-improve and thereby offer increased efficiency and effectiveness.

(read full article on Machine Learning here)


Companies like Purisma and Siperian offer machine learning techniques built into their software.

A primary goal of machine learning would be to reduce the amount of manual review needed to determine matches and continuously improve the software's ability to accurately detect and consolidate duplicate records.

An open source tool that can be used for probabilistic record matching is Febrl (Freely Extensible Biomedical Record Linkage). Written in Python anyone can download this from sourceforge.net and get your feet wet with probabilistic matching.

Friday, January 05, 2007

CDI - Matching Engines

Another tip from CDI expert Jill Dyche on the subject of matching engines and whether or not to base your CDI software decision entirely on the quality of the match engine:

Here are some other things to keep in mind when assessing matching engines:

  • Test with lots of real data; compare and benchmark results. Organizations testing CDI hubs should test with as much data as possible to get a more real-world test of the system, Levy said. DataFlux's Gidley also recommends profiling data sources to assess the accuracy and completeness of data. This can help with tuning the matching engine's business rules. For example, if 50% of the phone number fields in a database are empty, it might not be a good matching attribute.
  • Consider the interface. When a system isn't sure whether records match, it generally refers the matter to a human data steward to make the call. So the interface for data stewards is an important part of a tool decision, Gidley said.
  • Think globally and futuristically. Language differences, industry-specific requirements, and future infrastructure plans -- such as moving to a service-oriented architecture -- can also affect matching engine choices, according to Dyche.
Overall, Dyche said, the matching engine should be only a part of the overall CDI tool choice.

"Matching is one of many decisions to make," Dyche said. "When we see these vendor bake-offs and companies get down to [which CDI vendor] has the most accurate match, that's still only one component of the decision."

So, in some cases, the CDI tool with the most accurate matching engine might not be the final choice. Companies must consider the big picture, including data volumes, processing speed and functional requirements, Dyche said.

CDI - Project Research

A great post about CDI project research and what you should ask yourself before diving too deep into the CDI pool covers the following:

What is the "need, pain or problem" that we're trying to solve?
What are our requirements, both from a business as well as a functional perspective?
What data sources have critical customer information in them?
What's the current system of record for customer data?
Who are the current de facto data owners in the company?
What are the ideal matching algorithms for our particular data?
What is the potential impact on existing technology architecture and systems?
How and when will data stewardship be addressed?

"Eight must-ask questions for CDI projects by Jill Dyche


Tuesday, January 02, 2007

Matching Algorithms for CDI

It generally understood that between 2%-5% of a customer database will contain undetected duplicates after a standard merge/merge routine is run. As stated in CRM Today, most merge-purge algorithms are 20 years old...

Most merge/purge processes were developed over 20 years ago and were never conceived to recognize the fluidity of movement, name change, and channels in which customers interact today. Even the most advanced de-duplication processes use character based logic and look up tables that are ill-equipped to assess the totality of a customers’ name and address permutations that accumulate through multiple customer interaction channels. These processes are easily deceived by minor variations in the name and address elements such as married/maiden, nick names, typos, and mis-keys. A typical file will contain 2 to 5% unidentified duplicate customers after a standard merge/purge process.
Instead of the common approach of only using one matching algorithm (I am guilty of this one) modern approaches are utilizing many algorithms to isolate duplicate records.
No single algorithm can efficiently and effectively power a matching technology due to the multiple culprits of customer identity and data quality error. Advanced solutions incorporate not one, but several advanced matching algorithms, each designed to group records into temporal data sets for the purpose of bringing visibility to distinct patterns of repetitious error. Once patterns of error are identified, the records can be referenced to consumer data sources, allowing for the remediation of the error and recognition of the true identity of the customer.
An integral part of any CDI product is its matching capability. Match rules will vary from organization to organization so using a standard template or built-in rules usually will not suffice if you want thorough duplicate detection and handling.

Firstlogic (now Business Objects) has a sophisticated match engine and beyond the standard match capabilities are "Extended Matching" which allows the user to set up custom rules for different match scenarios. I believe that simply using rule based matching you can solve 80% of your data consolidation issues.

Companies like Purisma or Siperian offer much more sophisticated match engines that utilize match clusters and larger "match footprints" which ease the process, but for the most part, if you know what you are trying to do, any rule based matching engine will do. And remember:
"The computer is no better than the organization that feeds it." - L. Ron Hubbard
The moral is first work out all your match rules and then see if you can solve your problems using your existing match engine software before looking elsewhere to solve these match related problems.

Friday, December 29, 2006

CDI - Build or Buy?

Organizations with a central HQ and regional offices, must have some form of CDI in order to accurately understand their customer base. Otherwise you are left with disparate sets of disrelated data, unlinked and unconsolidated, making analysis and effective marketing nearly impossible. So once CDI as a topic is understood, the next question becomes - Build or Buy? After travelling down the "build" path for 2 years I wish I had researched and implemented a commercial product just to avoid the headaches alone...

However, with all that water under the bridge, it would be nice to be able to simply "plug-in" the missing parts to make my CDI solution complete.

I recommend buying a solution outright, even though the cost may be overwhelming at first, it will pay off if your organization is doing any volume of mailing - and will probably pay itself back in postage saved alone.

Here are the key questions that should be asked of a CDI vendor if you are looking to buy:

* Since systems rarely share identifiers, does the solution score and match data taking advantage of all attributes that aid in the matching process using likelihood statistical theory for the highest levels of accuracy? State-of-the-art systems use "probabilistic algorithms" to compare attributes one by one and produce a weighted score for each pair of records. The higher the score, the more likely the records represent the same person. This method improves matching accuracy by using weights that are specific to an organization's data.

* Does the vendor provide analysis based on your own real-world data? Premier providers conduct frequency-based file analysis to provide weighting and thresholds specific to a customer's data. By using your own data, a better match is possible than by using generic criteria and arbitrary weights for each attribute. The data can be studied and tuned to recognize that a match on John Smith in the Bronx, NY, contains a more trusted matching value than a match on John Smith in Minnesota.

* Does the provider offer a way to capture and maintain a complete history of changes to attribute values? Such a method of "complete versioning" improves accuracy and has the ability to make the correct decisions on linking data even as it constantly changes due to marriage, divorce, new address, new phone number, etc.

* Does the solution enable you to establish the right accuracy and identification levels for your application and budget? Managing data quality is a business decision, so consider whether you need automated identification of results to ensure faster customer service, for example, or a solution that allows manual review of data to capture fraudulent customer activity, such as duplicate insurance claims.

* Can the solution overcome multiple identifications and data discrepancies across sources? Common obstacles to customer identity include transpositions, misspellings, nicknames, aliases, address inconsistencies and identity misrepresentations, all of which can occur when customer data flows into the company through multiple touchpoints. A strong CDI product should be able to keep data up to date and synchronized across the enterprise.

* Can you use the same matching technology in order to maintain all your relationships: for example, individuals, households and companies?
(read rest of article here)


How to create that Golden Master

The concept of a centralized view or 360 degree view of a customer is often strived for but the "name, want and get" is not always figured out. Most companies will name what they are looking for, some fall short in getting the board to want the solution and many lose it on figuring out how to get it done.

VP of Siperian describes the need for assigning reliability factors to the different sources of data as some sources may have more accurate data:

In order to deliver a “golden” or master record for each customer and its various affiliations, a system must dynamically assess reliability across all data sources – based on user-defined parameters and intrinsic data properties – and ensure that only the most reliable content survives at the cell-level of the master record. For instance, if the call center begins collecting email addresses when confirming orders, this data attribute may be more reliable than the email addresses submitted by customers at the website. The ability to rapidly adjust the system to survive the call center email address over the website email address is a critical architectural component of any CDI system. Moreover, such cell-level survivorship for data reliability must be built into the core product architecture and should not be sacrificed as the customer hub scales to millions of customers. Ultimately, how well the end-users accept a customer data hub depends on sustaining high level of data reliability, even as the hub grows in volume or as new data sources are added.
In looking into different CDI solutions, you must look into how the data hub is structured, if they have configurable rules for loading and merging and if they have a robust Data Steward. Realize that data stewardship is the way all 'exceptions' get handled. If you do not separate out the confident updates from the questionable ones, you will have a poor foundation that will eventually lead to a polluted database.

A business cannot implement an operational customer hub in the absence of data stewardship ― as soon as data begins to flow through the supported business processes, exceptions and errors begin to flow as well. Therefore, any customer hub acting as a data integration platform must offer business capabilities to monitor and handle such exceptions either by business analysts and end-users or by anyone designated as a data steward.
...
Often managing such exceptions requires full user interfaces for complex data stewardship tasks such as investigating the history and lineage of certain master records in question. This may be the only way to ensure that the user acceptance and data hub reliability remains high. In other circumstances, an enterprise may choose to build a specific user interface against the programming interfaces of the master hub in order to suit its needs. In either case, an adaptive solution must deliver rules-based configurability with best-in-class data stewardship consoles as well as programming interfaces to handle all data exception and reliability needs.
I've worked on custom CDI projects before CDI was called CDI and can attest that the Data Stewardship interface will make or break your CDI project. This should not be underestimated.

The last point data export back to original sources. This is where you exchange your centralized view with the sources and provide them with your expanded view to assist them in better understanding your customers. If you have done a good job, they will love you, if you haven't you will be public enemy number one. They think their data is "better than yours", "why did you change my address", "you merged two customers into the same one!" and other rantings will be sent your way if you have not done a good job.

You should have a well thought out strategy including what data elements you will send back to sources and you should allow them to decide whether or not they want your data.

Often, certain data attributes (such as privacy preferences) need central control and exception handling whereas other attributes are best left under local management. In addition, security and access to data attributes in the hub will vary by individual roles within each organization and by organization at large. In fact, to support the broad range of business requirements across business lines, there may be multiple data governance regimes required for different data attributes, all within a single enterprise.

An adaptive approach must be based on a distributed architecture whereby multiple hubs can be deployed to integrate different data sources and support different processes, yet be able to share data across one another based on any number of hub-and-spoke or peer-to-peer governance regimes. This offers a line of business yet another dimension of flexibility to share some but not all data – each based on its own data reliability and governance policies. With full rules-based configurability and data stewardship interfaces, a broad range of data governance regimes can be supported.

In summary, data must be the central focus of any CDI project, and data reliability, stewardship and governance regime must never be an after-thought of a comprehensive CDI solution. Enterprises must closely review the details of a vendor’s offering in this area to reduce their risk of project failure and the total cost of CDI implementation.


Friday, December 22, 2006

Customer Data Integration (CDI) Can't Decipher It

I'm drowning in the sea of Customer Data Integration solutions, Data Librarians, Data Stewards, Registry hubs, Persistant hubs or Hybirds. Above is a good review of the basics of the problem domain. Key players are the Oracle Customer Data Hub, Siperian, Purisma and possibly the recent Sun aquisition - SeeBeyond.


"Oracle leads in customer data integration. Oracle has assembled the broadest set of components, from data quality, to matching, to customer key management, to process integration, to ongoing monitoring and management."—Forrester Research

Customer knowledge is the lifeblood of the enterprise. And customer knowledge begins with a unified, reconciled source of high-quality customer data—provided only by the Oracle Customer Data Hub.
Oracle Customer Data Hub is a fully integrated customer data management solution that centralizes, de-duplicates, and enriches your customer data, continuously synchronizing with all your data sources, to give you a single view of your customers. As new data comes in, reporting accuracy grows, analytics become more valuable, employee productivity increases, and day-to-day customer relationships improve.
Reading Jill Dyche's new book, Customer Data Integration is my life preserver. Talking to salespeople has led to further confusion and contradictory statements about each others products.

Gartner's findings of May 2006 on CDI may already be outdated with the fastly evolving market.